AgentOS



AgentOS is an open-source TypeScript runtime for AI agents that remember, adapt, and write their own tools. Apache-2.0.
npm install @framers/agentos
The runtime carries the parts of an agent that should outlive a single chat completion. Persistent cognitive memory with Ebbinghaus decay and eight neuroscience-grounded mechanisms (reconsolidation, retrieval-induced forgetting, involuntary recall, metacognitive feeling-of-knowing, temporal gist, schema encoding, source-confidence decay, emotion regulation), each grounded in primary cognitive-science literature. The eight run when the memory manager is given a cognitiveMechanisms config, and each can be switched off there. Optional HEXACO personality traits that write directives into the system prompt and, given to a cognitive memory manager, modulate encoding strength, working-memory capacity and the format of recalled memories. Six multi-agent orchestration strategies (sequential, parallel, debate, review-loop, hierarchical, graph). Two-phase streaming guardrails. A voice pipeline that runs streaming speech-to-text, turn detection, the agent's reply and streaming text-to-speech over one transport, with a barge-in handler for speech over the reply. One dispatch interface across 13 LLM providers.
On the full runtime, AgentOS.create({ emergent: true }) gives its agents a forge_tool tool for writing a tool mid-task; the lightweight agent() helper accepts emergent: true and does not activate it. A forged tool declares JSON Schema input and output and test cases, and either chains existing tools or, when emergentConfig.allowSandboxTools is set, runs agent-written JavaScript. A separate LLM-as-judge scores code safety, test correctness and determinism, and on approval the tool joins the session's catalog. Sandboxed code runs in an in-process node:vm context, which Node's documentation says is not a security mechanism, or in a QuickJS WebAssembly instance per call. A tool used 5 or more times with confidence 0.8 or higher that a two-reviewer panel approves is promoted to agent tier, which a runtime with a storage adapter keeps across restarts; exportToolAsSkillPack() writes a forged tool out as a SKILL.md. In a hierarchical agency with emergent.enabled, the manager can call spawn_specialist to add an agent to the roster mid-run, and with emergent.judge: true a judge reviews each synthesized agent before it joins.
100+ first-party extensions (channel adapters, tool packs, guardrail packs) and 88 curated SKILL.md skills ship as separate packages, each with a registry package that loads them. Extensions load from the manifest a host passes to AgentOS.create({ extensionManifest }): createCuratedManifest() from @framers/agentos-extensions-registry builds one from the curated extensions that are installed, and a runtime without a manifest loads none. Skills reach an agent through agent({ skills }) or the runtime's capability discovery sources.
The benchmarks below measure this runtime against alternative memory libraries; each result names its reader model.
85.6% on LongMemEval-S at $0.0090 per correct, with a per-category reader router: gpt-4o answers temporal-reasoning and single-session-user questions, gpt-5-mini the other four types. With gpt-4o reading every question, the same retrieval scores 84.2%, level with Mastra Observational Memory (84.23%) at that reader. AgentOS ships under Apache-2.0, free to install, fork, and self-host.
70.2% on LongMemEval-M at $0.0078 per correct on the 1.5M-token / 500-session haystack — the only open-source library on the public record above 65% on M with publicly reproducible methodology. Competitive with the strongest published M results in the LongMemEval paper (Wu et al., ICLR 2025: round Top-5 65.7%, session Top-5 71.4%, round Top-10 72.0%).
Benchmarks reference · Reproducible run JSONs · SOTA writeup
How recall works
AgentOS routes memory with small LLM-as-judge classifier calls, up to three per query. When the host runs the QueryClassifier gate, trivial queries (greetings, small talk, general knowledge answerable from context) skip retrieval. The MemoryRouter classifies the query's category and picks the retrieval architecture for it, selectReader() picks the reader model from that category with no further call, and the ReadRouter picks the read strategy.
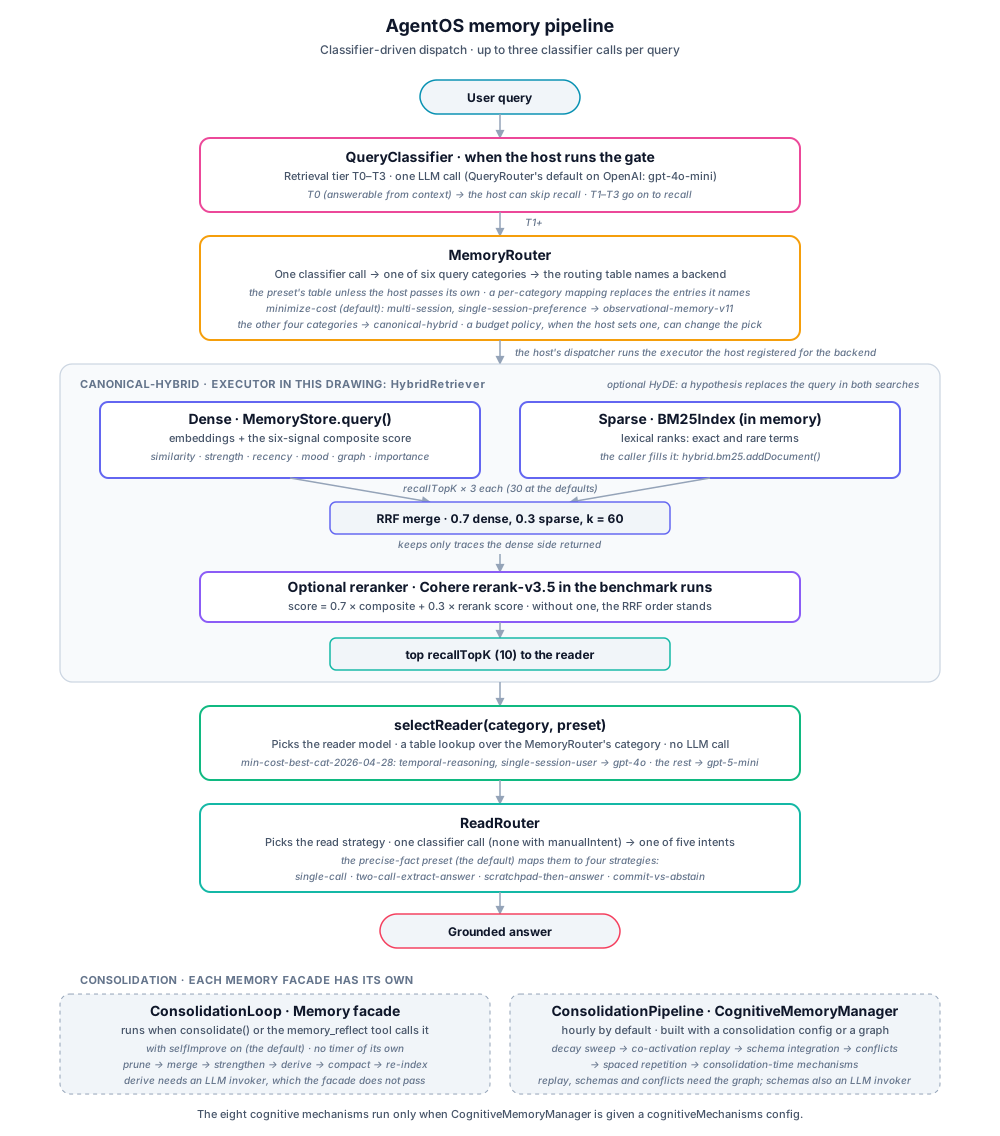
| Stage | Primitive | Decision per query |
|---|---|---|
| 1 | QueryClassifier | T0/none · T1/simple · T2/moderate · T3/complex |
| 2 | MemoryRouter | canonical-hybrid · observational-memory-v10 · v11 |
| 3 | selectReader() (ReaderRouter) | gpt-4o vs gpt-5-mini per category, from Stage 2's category |
CognitivePipeline.recallAndRead() makes two classifier calls per query, the MemoryRouter's and the ReadRouter's, and the gate adds one when the host runs it; Stage 3 is a table lookup. With the min-cost-best-cat-2026-04-28 preset, the reader lookup sends four of the six LongMemEval categories to gpt-5-mini, whose list price is a tenth of gpt-4o's per input token and a fifth per output token, and lifts single-session-preference by 10 points in the benchmark runs; the gate gives queries that need no memory a path that skips retrieval. Reproducible run JSONs in agentos-bench.
Where to start
- High-Level API — the one-import functions:
generateText(),streamText(),generateObject(), image, video and audio generation,agent(),gmi()andagency(), how each call picks its provider, and the full runtime'sAgentOSclass. - Cognitive Memory — why memory should forget. Eight neuroscience-grounded mechanisms, primary-source citations, the consolidation loop. The story is the page.
- GMI architecture — the Generalized Mind Instances (GMIs) that the full runtime's
GMIManagerbuilds for its sessions and thatgmi()andagent({ runtime: 'gmi' })build for their sessions and theirgenerate()andstream()calls; a plainagent()builds none. What a GMI holds, the turn loop, the completion gateway that gives the GMIs ofgmi()their fallback hops (the full runtime's GMIs call their provider directly), and the chunks a turn streams. - System Architecture — the runtime's layers and the eleven top-level directories of its source.
- Deep Research — the 3-phase pipeline behind sourced answers.
- Emergent Capabilities — runtime tool forging, judge approval, sandboxed execution.
- Examples Cookbook — 17 recipes for agents, agencies, query routing and orchestration, and a table of 24 of the runnable files in
examples/. - TypeDoc API — the reference TypeDoc generates from the package's root entry point,
@framers/agentos(src/index.ts). A symbol exported only from a subpath, such asMemoryRouterfrom@framers/agentos/memory-router, has no page there.
Paracosm — the swarm-simulation companion
Paracosm is an agent-swarm simulation engine I built on AgentOS. Define a world as JSON, run it with HEXACO-typed leaders directing a swarm of specialists and ~100 personality-typed cells, and watch their decisions diverge into measurably different outcomes from an identical seed. Reproducible, forkable, replayable. The swarm is first-class on the API: RunArtifact.finalSwarm, paracosm/swarm helpers, GET /api/v1/runs/:runId/swarm for HTTP consumers.
The reference scenario ships as Mars Genesis — a 100-colonist Mars settlement running from 2035 to 2083 across six turns. Two leaders, same seed, different HEXACO profiles, different futures. Try it live.
Live demo · GitHub · npm · API reference
Wilds AI Discord for questions, feedback, community. Contact AgentOS for partnerships, security disclosures, enterprise inquiries.