Memory System Overview
A study-grade walkthrough of the AgentOS memory stack: ingest, recall, read, decay, consolidation, multimodal, the classifier-driven dispatch pipeline, the Cohere neural rerank, the LLM-as-judge orchestration tiers, and the path from "embed everything" to 85.6% on LongMemEval-S at $0.0090 per correct with full provenance.
TL;DR
AgentOS memory composes six operations per turn, and the central design decision is which of them run on a given query.
Up to three classifier calls per query: the QueryClassifier gate when the host runs it, the MemoryRouter's and the ReadRouter's. A hybrid retrieval pipeline: BM25 + dense retrieval, fused by rank, with an optional reranker (Cohere rerank-v3.5 in the benchmark runs). A six-signal cognitive composite score on every dense hit. Ebbinghaus decay applied whenever a trace's strength is read. A consolidation pass that prunes, merges, and re-strengthens traces. Underneath, a portable SQL brain — @framers/sql-storage-adapter — that runs on SQLite (better-sqlite3), Postgres (pg + pgvector), IndexedDB (sql.js, browser/PWA), Capacitor SQLite (iOS/Android), Electron IPC, or in-memory, without a callsite change.
Same code on every storage backend, one set of benchmarks: 85.6% on LongMemEval-S at $0.0090 per correct, 70.2% on LongMemEval-M.
| Headline | Number | Compared with |
|---|---|---|
| LongMemEval-S accuracy (gpt-4o and gpt-5-mini readers routed per question type, N=500) | 85.6% [82.4%, 88.6%]; 84.2% with gpt-4o on every question | Mastra OM gpt-4o 84.23%, EmergenceMem Internal 86.0% (closed-source SaaS), Supermemory gpt-4o 81.6% |
| LongMemEval-S cost per correct | $0.0090 | EmergenceMem Simple Fast measured $0.0581 (6.5x more) |
| LongMemEval-S p50 latency | 3,558 ms | EmergenceMem Internal 5,650 ms |
| LongMemEval-M accuracy (1.5M-token haystacks, N=500) | 70.2% [66.0%, 74.0%] | LongMemEval paper Top-5 round 65.7%, paper Top-10 round 72.0%, AgentBrain (closed) 71.7% |
| Open-source memory libraries on LongMemEval-M above 65% | AgentOS only | Every other vendor (Mem0, Mastra, Supermemory, Hindsight, Zep, EmergenceMem, MemMachine, agentmemory) publishes only the easier S variant |
| License | Apache-2.0 | EmergenceMem Internal closed SaaS, EmergenceMem Simple Fast no LICENSE file |
The next sections explain each piece, why it earned its place, and which adjacent ideas were tested and dropped.
Markdown memory (the LLM wiki). This overview covers the vector and graph memory stack. For the markdown-as-source-of-truth model, where the agent reads and rewrites its own markdown knowledge base, see Soul Files & the Markdown Memory Wiki.
How it connects (60-second summary)
The whole stack is up to three small classifier calls plus a hybrid retriever, on top of a SQL-backed brain that a consolidation pass maintains: CognitiveMemoryManager runs its ConsolidationPipeline, which opens with a decay sweep, on an hourly timer (consolidation.intervalMs, off with consolidation.enabled: false), and the Memory facade runs its ConsolidationLoop when consolidate() is called. The calls depend on the host's path: the QueryClassifier gate's call when the host runs the gate (a T0 query ends there when the host skips recall on it), then the MemoryRouter's and the ReadRouter's. Every concept that sounds like a separate thing in this doc plugs into one of those four parts.
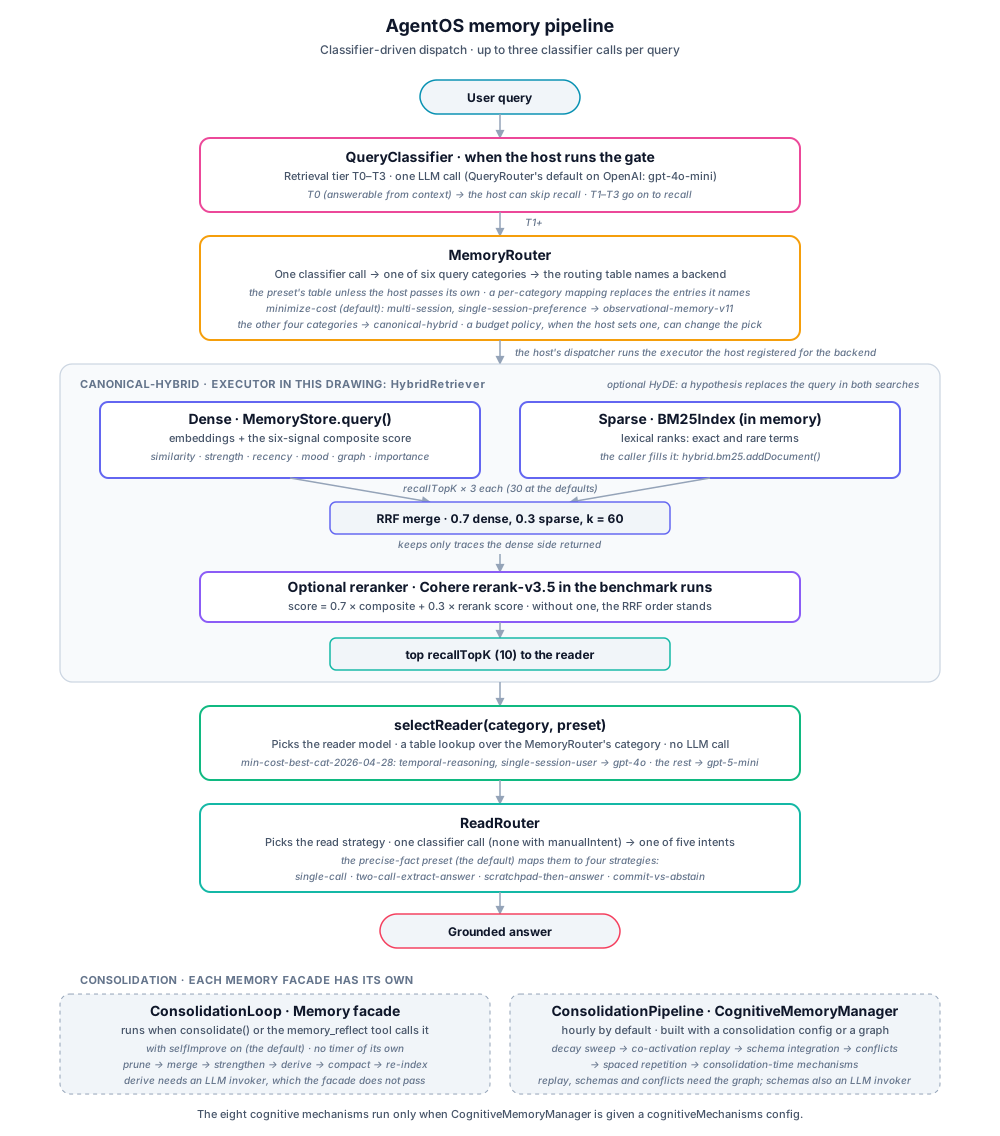
Each facade has its own consolidation, drawn as its own box in the diagram above and in the end-to-end flow below: ConsolidationLoop serves the Memory facade when consolidate() or the memory_reflect tool runs it (prune, merge, strengthen, compact, re-index; its derive step needs an LLM invoker, which the facade does not pass), and ConsolidationPipeline serves CognitiveMemoryManager on its timer, hourly by default. The eight mechanisms run only when CognitiveMemoryManager is given a cognitiveMechanisms config (Memory Consolidation, The Eight Cognitive Mechanisms).
Where a verbatim archive is wired, it is write-ahead: the temporal-gist mechanism (with an archive in its config) and MemoryLifecycleManager wait for the archive write before changing a trace, and abort if it fails. CognitiveMemoryManager passes its archive to neither the temporal-gist mechanism nor its consolidation pipeline, so its gisting keeps no archived copy (see Memory Consolidation).
If a term in the doc below sounds new, here's where it plugs in:
| You hear... | It's the... | And it lives in... |
|---|---|---|
| BM25 | lexical leg of canonical-hybrid | HybridRetriever's own in-memory BM25Index, which the caller fills (hybrid.bm25.addDocument()) |
| FTS5 / tsvector | the SQL brain's full-text index over memory_traces | the adapter's IFullTextSearch; the memory_search tool queries it, and the add, update and merge paths keep it in sync |
| Cohere rerank-v3.5 | cross-encoder rerank pass after RRF merge | the retrieval signal that moved accuracy most in the benchmark runs; v4.0-pro tested and dropped |
| HyDE | hypothesis-then-embed retrieval mode | optional retrieval augmentation; on for M, off for S |
| Six-signal composite | the cognitive memory layer's scorer on top of similarity | encoding strength, recency, mood, graph, importance, similarity |
| Ebbinghaus decay | the forgetting curve that ages every trace | runs at retrieve time; consolidation prunes traces below threshold |
| HEXACO modulation | personality vector that biases encoding strength, working-memory capacity and the cognitive mechanisms | optional; runtime works personality-neutral by default |
| Spreading activation (ACT-R) | graph BFS that raises the score of retrieved traces linked in the memory graph | seeded by the top five retrieved traces; adds no trace retrieval did not return |
| OM-v10 / OM-v11 | observational-memory backends MemoryRouter can dispatch to | below canonical-hybrid with a semantic embedder in the benchmark runs; kept for cost-tolerant workloads |
| LLM-as-judge | how each classifier labels a query: QueryClassifier a tier (T0-T3), MemoryRouter a memory category, ReadRouter a read intent | one classifier call each; ReadRouter.decide() makes none when the host passes manualIntent; selectReader() reuses the MemoryRouter's category |
| Tiered presets | shipped routing tables — minimize-cost / balanced / maximize-accuracy | calibrated from Phase B per-category cost-accuracy points |
| Adaptive variant | AdaptiveMemoryRouter self-calibrates from your workload | use when your category mix or reader differs from LongMemEval-S |
| Storage substrate | @framers/sql-storage-adapter — same brain code, multiple backends | SQLite default, Postgres / IndexedDB / Capacitor / Electron all swap in |
| Eight cognitive mechanisms | optional neuroscience-grounded layers (RIF, gist, schema, etc.) | each maps to a published paper; HEXACO-modulated; individually toggleable |
The deep sections below trace each of those into the actual code paths and the Phase B run JSONs that justify the choice.
What AgentOS Memory Actually Is
A "memory library" can mean very different things. AgentOS ships:
- A storage substrate (
Memory.createSqlite()/Memory.createPostgres()/Memory.createWithAdapter()): traces, embeddings, FTS5 (or Postgres tsvector + GIN) index, knowledge graph, memory graph, retrieval feedback, consolidation log, and an optional verbatim archive — all sitting on top of@framers/sql-storage-adapter. The adapter auto-selects the best backend per runtime (better-sqlite3 on Node, sql.js+IndexedDB in the browser, Capacitor SQLite on mobile, Postgres in production, in-memory for tests) so the same brain code runs everywhere. Zero infrastructure for the SQLite default, scales to multi-tenant Postgres without rewriting a callsite. - A cognitive layer (
CognitiveMemoryManager): personality-modulated encoding, Ebbinghaus decay, Baddeley working memory, ACT-R spreading activation, six-signal retrieval scoring, optional observer/reflector pipelines for conversation compression. - A classifier-driven orchestration layer (the Cognitive Pipeline): small classifier calls (the QueryClassifier gate, the MemoryRouter and the ReadRouter) route each message through the cheapest, most accurate path for that query.
- A benchmark harness (
@framers/agentos-bench): the same primitives, run against LongMemEval-S, LongMemEval-M, LOCOMO, BEAM, and a battery of cognitive-mechanism micro-benchmarks. Per-case run JSONs at fixed seed, 95% confidence intervals from 10k bootstrap resamples, judge false-positive-rate probes per benchmark.
Most "memory libraries" stop at layer 1 with a vector index pinned to one backend. AgentOS treats backend portability and orchestration (layer 3) as first-class, which is where it pulls ahead on the cost-accuracy frontier without sacrificing reproducibility or deployment flexibility.
The Storage Substrate (@framers/sql-storage-adapter)
The brain doesn't speak SQLite directly. It speaks the StorageAdapter interface of @framers/sql-storage-adapter, an abstraction over the concrete backends below, selected per runtime:
| Adapter | Package | Where it runs | Use case |
|---|---|---|---|
better-sqlite3 | better-sqlite3 | Node, Electron, CLI | Local agents, dev, CI, single-process production |
postgres | pg (with pgvector) | Hosted Postgres, RDS, Supabase | Multi-tenant SaaS, shared connection pools, fan-out |
electron | bundled | Electron desktop apps | IPC bridge between main/renderer, multi-window WAL, auto-migrations |
indexeddb | bundled (sql.js wrapper) | Browsers, PWAs | Offline-first web apps with 50 MB to 1 GB+ quota |
sqljs | sql.js | Browsers, edge runtimes, native fallback | Pure WASM SQLite, no native deps, ephemeral by default |
capacitor | @capacitor-community/sqlite | iOS, Android | Native mobile SQLite with optional encryption |
memory | built-in | Unit tests, sandboxes | Zero-dependency, single-process, non-durable |
createDatabase() inspects environment signals (window.indexedDB, process.versions.electron, Capacitor, etc.) and picks the best adapter. Override by env var (STORAGE_ADAPTER=postgres) or by explicit priority list:
const db = await createDatabase({ priority: ['better-sqlite3', 'sqljs'] });
How memory plugs into the adapter
Three entry points on the Brain class:
import { Brain } from '@framers/agentos/memory';

// 1. Default — SQLite file per agent
const sqliteBrain = await Brain.openSqlite('./brain.sqlite');

// 2. Postgres for multi-tenant production
const pgBrain = await Brain.openPostgres(
  'postgresql://user:pass@host:5432/db',
  { brainId: 'companion-alice', poolSize: 10 },
);

// 3. Bring your own adapter (share connection pool with the rest of your app)
import { createDatabase } from '@framers/sql-storage-adapter';
const adapter = await createDatabase({
  postgres: { connectionString: process.env.DATABASE_URL },
});
const sharedBrain = await Brain.openWithAdapter(adapter, { brainId: 'companion-alice' });
Three things the adapter abstracts away so the brain code stays identical:
- SQL Dialect.
INSERT OR IGNORE,json_extract(...),ifnull(...),PRAGMAget translated automatically between SQLite and Postgres via theSqlDialectinterface. The brain writes one set of queries; the dialect rewrites them per backend. - Full-text search.
IFullTextSearchabstracts FTS5 (SQLite with the Porter tokenizer), FTS4 (sql.js and the IndexedDB adapter, whose SQLite builds have no FTS5) and tsvector + GIN (Postgres) behind onecreateIndex/matchClause/rankExpression/relevanceOrder/rebuildCommandAPI, so the brain'smemory_traces_ftsindex and thememory_searchtool's query work on both backends without branching. The brain passes?as the query placeholder to every fragment: the adapter sends a statement that already holds a$nplaceholder as written, so a fragment left on its default$1would leave the statement's?unbound on Postgres. It also names the index by its own name in the join, never an alias: FTS4's rank,offsets(memory_traces_fts), takes the table's hidden column, which carries the table's name.HybridRetrieverdoes not read this index: its BM25 leg is a per-instance in-memoryBM25Indexthat the caller fills. - BLOB codec. Embeddings are stored as raw
Float32ArrayBLOBs.NodeBlobCodecusesBuffer;BrowserBlobCodecusesDataView. The 1536-dimtext-embedding-3-smallvector takes ~6 KB per trace on disk and round-trips byte-identical across backends.
Multi-tenant Postgres mode
In Postgres mode every brain-owned table carries a brain_id discriminator:
CREATE TABLE memory_traces (
  brain_id    TEXT  NOT NULL,
  id          TEXT  NOT NULL,
  type        TEXT  NOT NULL,
  scope       TEXT  NOT NULL,
  content     TEXT  NOT NULL,
  embedding   BYTEA,
  ...
  PRIMARY KEY (brain_id, id)
);
Two brains in the same database stay isolated by the discriminator. SQLite mode skips the column because each brain has its own file.
The first call to Brain.openPostgres (or openSqlite) on an existing v1 database runs an idempotent v1→v2 migration that adds brain_id to every brain-owned table and updates primary keys to (brain_id, id). Postgres uses ALTER TABLE ADD COLUMN + ALTER TABLE ADD PRIMARY KEY; SQLite uses the recreate-table dance. Subsequent opens are no-ops.
A pg_advisory_xact_lock per brainId serializes concurrent first-opens so two workers booting the same brain don't race on schema migration.
Different brains boot in parallel and set up the tables they share at the same time. An open whose CREATE ... IF NOT EXISTS loses the race to another open's, which Postgres reports once the other commits the object, runs that step again and finds the object, as many times as the step loses (up to eight runs). The Postgres backend page gives the errors it reads as a lost race.
Pool sizing
Sharing a StorageAdapter across N brains shares the underlying connection pool. Five brains opened against a max: 10 pool compete for the same 10 connections; one slow query starves the others. Size for total concurrent query load across all brains, not per-brain. For high-fan-out deployments (one process serving 50+ active brains), use a dedicated pool per brain via Brain.openPostgres(connStr, { brainId, poolSize: N }) instead of sharing.
Portable export and import
Live storage and portability are decoupled. Run Postgres in production, snapshot to SQLite for backup or fork:
const liveBrain = await Brain.openPostgres(connStr, { brainId: 'alice' });
await liveBrain.exportToSqlite('/tmp/alice-snapshot.sqlite');

// Later, fork into a different brain (importing rewrites brain_id)
const forkBrain = await Brain.openPostgres(connStr, { brainId: 'alice-fork' });
await forkBrain.importFromSqlite('/tmp/alice-snapshot.sqlite');
The adapter's IDatabaseExporter ships SqliteFileExporter (VACUUM INTO) and PostgresExporter (pg_dump) for backend-native export paths. Each copies the whole database, every brain in it included; the memory facade's SQLite export (mem.export(path, { format: 'sqlite' })) goes through Brain.exportToSqlite and writes one brain's rows from either backend.
Why this matters for the benchmarks
Every LongMemEval-S / LongMemEval-M run in the bench uses the SQLite adapter because the bench is a single-process harness measuring a single brain at a time. The same brain code runs over Postgres. The SQL dialect translation, full-text search abstraction, and BLOB codec are designed to preserve query semantics across backends, so retrieval-quality metrics (recall@K, NDCG@K, MRR) are expected to transfer; latency floors differ (Postgres has higher per-query network overhead than embedded SQLite, but scales horizontally on connection count where SQLite serializes).
For the full adapter architecture, capability matrix, and lifecycle hooks, see @framers/sql-storage-adapter (README, ARCHITECTURE.md, PLATFORM_STRATEGY.md).
The End-to-End Flow
A query costs up to three classifier calls: one in QueryClassifier when the host runs the gate, one in MemoryRouter and one in ReadRouter (CognitivePipeline.recallAndRead() makes the last two; a host that calls ReadRouter.decide() with manualIntent skips the ReadRouter's). The reader-model lookup, selectReader(), reuses the MemoryRouter's category and makes no call. Trivial queries (greetings, small talk, questions answerable from context alone) end at Stage 1 with no retrieval when the host skips recall on T0.
Stage 0: Ingest
IngestRouter classifies incoming content into one of six kinds and picks an ingest strategy:
| Content kind | Typical strategy | Cost (illustrative) |
|---|---|---|
| short-conversation (1-3 turns) | raw-chunks | $0.0001 |
| long-conversation (extended thread) | observational | $0.020 |
| long-article (blog, paper) | summarized (Anthropic contextual retrieval) | $0.005 |
| code (source files, configs) | summarized | $0.005 |
| structured-data (CSV, JSON) | raw-chunks | $0.0001 |
| multimodal | raw-chunks (every preset; the text representation is indexed) | $0.0001 |
Why this matters: a 3-turn chat snippet does not justify the LLM cost of observation extraction. A 50-turn customer support thread does. Picking the wrong strategy at ingest costs accuracy or money downstream. The bench's Phase B sweeps showed observational ingest on short conversations regresses on every category and pays a 200x cost premium for nothing.
The strategies map to canonical patterns in the literature:
summarizedis Anthropic's contextual retrieval (every chunk prepended with a dense session/document summary before embedding).observationalis Mastra's Observational Memory (LLM-extracted observation log replacing raw turns).fact-graphis the original Mem0 v2 / Hindsight pattern (typed entity-relation graph + facts).hybridruns raw + summarized + observational in parallel for cost-tolerant workloads with heterogeneous retrieval needs.skipdiscards content entirely (used for ephemera that should not enter long-term memory).
Stage 1: QueryClassifier (the memory-or-not gate)
QueryClassifier is the novel piece most memory libraries skip. It assigns every incoming query a tier:
| Tier | Meaning | What runs |
|---|---|---|
| T0 | answerable from context alone | no retrieval, no embedding, no rerank |
| T1 | simple recall | vector search over the corpus |
| T2 | moderate recall | a 15-chunk vector search, graph expansion when enabled, a rerank down to 5 |
| T3 | complex synthesis | the query split into sub-queries and searched one by one, graph expansion when enabled, a rerank down to 10, deep research when enabled |
The built-in QueryRouter generates no HyDE hypothesis for T2 or T3. HyDE runs there only when a UnifiedRetriever built with a hydeRetriever is attached with setUnifiedRetriever().
T0 is the decision that saves the most. Greetings, small talk, general-knowledge questions ("what's 2+2"), and questions whose answer is already in the running context window do not need to touch the memory database. Skipping retrieval for those queries saves the embedding cost, the rerank cost, and reduces the answer latency from ~3.5s to whatever the reader's TTFT is.
The classifier is one call to classifierModel (by default the cheap model of the default provider, gpt-4o-mini for OpenAI) with corpus topics, recent conversation history, and optional tool names in context. Live demonstration: see the QueryRouter initialize a 1,720-chunk corpus across 50 topics and 333 sources on the agentos.sh demo gallery.
Stage 2: MemoryRouter (architecture dispatch)
MemoryRouter decides, per T1+ query, which retrieval architecture handles it. Its routing tables name three backends; the router only decides, and the host's dispatcher runs the chosen backend:
| Backend ID | What it does |
|---|---|
canonical-hybrid | BM25 + dense embedding + RRF merge, then an optional reranker (Cohere rerank-v3.5 in the benchmark runs) blended with the cognitive-memory composite score |
observational-memory-v10 | gpt-5-mini per-question classifier routes to canonical for single-session/temporal questions and to v5 Observational Memory ingest for knowledge-update/multi-session |
observational-memory-v11 | v10 plus a conditional verbatim citation rule appended to the OM reader prompt for knowledge-update and single-session-user categories |
The classifier emits one of six query categories, each captured from LongMemEval's category taxonomy:
single-session-user(SSU): a fact stated by the user in one session ("what's my email?")single-session-assistant(SSA): a fact the assistant said in one sessionsingle-session-preference(SSP): a stated preference ("I prefer dark mode")knowledge-update(KU): a fact that changed over time ("what's my current job title?")multi-session(MS): a fact requiring synthesis across sessions ("what topics did we discuss?")temporal-reasoning(TR): time-arithmetic questions ("how many days since X?")
Why route at all: per-category Phase B N=500 measurements show different architectures dominate different categories. Flat "always canonical-hybrid" loses 6.8 pp on multi-session. Flat "always OM-v11" loses 5.4 pp on single-session-assistant and pays a 1.7-1.8x cost premium on every other category. Per-query routing extracts the best of both.
Three shipping presets
| Preset | Strategy | Result on LongMemEval-S Phase B N=500 |
|---|---|---|
minimize-cost | cheapest Pareto-dominant per category. Originally MS+SSP routed to OM-v11 under the CharHash-era calibration. | 76.6% / $0.058 per correct (CharHash baseline) |
balanced | trade 1.6x cost for 10x latency wins on KU/TR | 74.5% / $0.205 per correct (sim) |
maximize-accuracy | highest-accuracy backend per category | 75.6% / $0.243 per correct |
The configuration behind the headline, however, is canonical-hybrid for every category paired with selectReader() dispatch and text-embedding-3-small. That hits 85.6% at $0.0090 per correct, which is +9 pp above the minimize-cost CharHash baseline because:
- Wiring
text-embedding-3-smallinstead of the bench's CharHash fallback. CharHash is a lexical-hash stub the bench falls back to when no embedder is configured. It is not the documented production path. Real consumers wire a real embedder; doing so on the same router lifts the same row from 76.6% to 83.2% (an extra +6.6 pp, concentrated on temporal-reasoning +14.5 pp and multi-session +14.5 pp, where semantic retrieval finds paraphrase-rich and multi-hop bridges that lexical hashing missed). - Dropping the
minimize-costpreset's MS+SSP-to-OM-v11 routing in favor of canonical-hybrid for all categories, paired with Stage 3 ReaderRouter dispatch. At gpt-4o reader, OM-v11 routing produces a mixed per-category effect: it costs SSP 13.4 pp (63.3% on OM-v11 vs 76.7% canonical) and gains MS 4 pp. The case-weighted aggregate favors canonical because SSP's 13.4 pp loss outweighs MS's 4 pp gain, and OM-v11's per-session observer pipeline imposes 60-120 seconds per OM-routed case, producing a 111,535 ms p95 in the prior 84.8% headline. Without OM-v11 routing, p95 drops to 7,264 ms (15.4x faster on the tail).
For sem-embed deployments, use canonical-only plus selectReader() dispatch. The minimize-cost preset table targets CharHash retrieval and shouldn't be used in sem-embed mode.
Self-calibrating variant
AdaptiveMemoryRouter takes a calibration sample list and derives the routing table from your own workload. Use it when:
- Your category distribution diverges from LongMemEval-S.
- Your reader, judge, or cost profile differs.
- You want the router to optimize for YOUR per-category cost-accuracy points instead of a static table baked from someone else's measurement.
Three preset rules: minimize-cost (cheapest backend within a 2pp accuracy tolerance of the best), balanced (best $/correct ratio), maximize-accuracy (highest meanAccuracy, ties broken by lower cost). 50-200 samples per (category, backend) cell are enough.
Stage 3: ReaderRouter and ReadRouter (read-stage dispatch)
Two sibling primitives at the read stage. They compose: the reader lookup picks the model, ReadRouter picks the strategy that model follows.
ReaderRouter (model dispatch)
selectReader(category, preset), exported from @framers/agentos/memory-router, is a table lookup over Stage 2's category (zero extra LLM calls) that names the reader model for the answer call; the host makes that call. Its tables come from per-category Phase B accuracies:
| Category | Best gpt-4o accuracy | Best gpt-5-mini accuracy | Pick |
|---|---|---|---|
| temporal-reasoning (TR) | 86.5% | 80.5% | gpt-4o (long-context arithmetic) |
| single-session-user (SSU) | 95.7% | 90.0% | gpt-4o (exact recall) |
| single-session-assistant (SSA) | 96.4% | 100% | gpt-5-mini |
| single-session-preference (SSP) | 76.7% | 86.7% | gpt-5-mini (+10 pp on SSP alone) |
| knowledge-update (KU) | 88.5% | 91.0% | gpt-5-mini |
| multi-session (MS) | 78.2% | 74.4% | gpt-5-mini (cost-Pareto, 12x cheaper) |
The shipping min-cost-best-cat-2026-04-28 preset routes 53% of LongMemEval-S queries to gpt-5-mini and 47% to gpt-4o. The single-session-preference lift alone is +23.4 pp on a reader-tier swap (63.3% gpt-4o → 86.7% gpt-5-mini at the same retrieval).
ReadRouter (strategy dispatch)
ReadRouter classifies a query+evidence pair into a read intent and picks a reader strategy:
| Intent | Strategy | Why |
|---|---|---|
| precise-fact | single-call | one reader call; clear evidence rules out ambiguity |
| multi-source-synthesis | two-call-extract-answer | claim extraction call followed by answer call (Emergence Simple Fast pattern) reduces distractor influence |
| time-interval | scratchpad-then-answer | explicit reasoning scratchpad for date arithmetic before the commit |
| preference-recommendation | verbatim-citation | quote the user's stated preference verbatim |
| abstention-candidate | commit-vs-abstain | binary commit/abstain gate before the answer attempt |
ReadRouter ships its own precise-fact, synthesis, and temporal presets. Workloads heavy in time-interval questions pick temporal; multi-doc Q&A picks synthesis.
Inside Canonical-Hybrid Retrieval
In agentos, HybridRetriever implements this pipeline over a MemoryStore, and a host wires it in as the canonical-hybrid backend of its dispatcher:
Query
  │
  ├──────────────────────────────┐
  ▼                              ▼
┌──────────────────────┐   ┌──────────────────────┐
│ Dense search         │   │ BM25 search          │
│ MemoryStore.query:   │   │ (in-memory BM25Index │
│ embeddings + the     │   │  the caller fills)   │
│ six-signal composite │   │                      │
└──────────┬───────────┘   └──────────┬───────────┘
           │ recallTopK × 3 each (30 at the defaults)
           ▼                          ▼
           └── RRF merge (0.7 dense, 0.3 sparse, k = 60) ──┘
                              │
                              ▼  optional reranker (Cohere rerank-v3.5
                              │  in the benchmark runs): score =
                              │  0.7 × composite + 0.3 × rerank score
                              ▼
                     top recallTopK (10) to the reader
Why each retrieval signal earns its place
- BM25 + dense embedding fusion: BM25 catches rare terms and exact matches that dense embeddings miss; dense embeddings catch paraphrase-rich and multi-hop bridges that BM25 misses. RRF (Reciprocal Rank Fusion) merges the two ranked lists by rank, so their score scales need not match.
- Cohere rerank-v3.5 cross-encoder: the cross-encoder reads (query, candidate) jointly and reranks the merged candidate pool. In the benchmark runs it moved accuracy more than any other signal: without it, top-K from BM25+dense alone misses bridge sessions and gets diluted by topically adjacent but irrelevant chunks. rerank-v4.0-pro was tested at full N=500 and regresses 1.0 pp at point estimate while costing more per call (see Negative Findings below).
- Six-signal composite: the dense side scores each hit on five signals besides similarity. Strength is the trace's encoding strength after Ebbinghaus decay. Recency favors traces accessed within about a day. Emotional congruence favors traces whose valence matches the current mood. Graph activation comes from spreading activation over the memory graph (0 without one). Importance is the trace's provenance confidence, scaled to 0.5–1.
The composite's weights are fixed defaults (Six-signal retrieval scoring); a recall's scoringWeights option replaces them for that call. Personality does not change them.
Embedder choice
text-embedding-3-small is the validated production default. Phase B negative finding: text-embedding-3-large (3072-dim) regresses 2.2 pp on accuracy AND adds a 20x latency catastrophe (avg 81,195 ms vs 4,001 ms baseline; p50 23x slower; p95 19x slower). Recall@10 is 0.984 vs 0.981 for text-embedding-3-small, so the larger embedding does not meaningfully lift retrieval recall on this benchmark; canonical-hybrid + Cohere rerank already saturates retrieval at the smaller model. Bigger embeddings cost compute for no benefit on this stack.
HyDE (Hypothetical Document Embedding)
HydeRetriever is an optional retrieval mode based on Gao et al. 2023. Instead of embedding the raw query, HyDE first asks an LLM to produce a plausible answer, then embeds the hypothesis and searches against that. The intuition is that questions and answers live in different regions of embedding space; a hypothesized answer is closer to stored answer-form documents than the original question is.
HyDE is a Pareto-cost win on LongMemEval-M temporal-reasoning (+3.7 pp at Phase B). It is not a win on LongMemEval-S or LongMemEval-M multi-session: at S scale the canonical pipeline already saturates retrieval and HyDE dilutes the rerank pool with hallucinated chunks; at M scale on multi-session, HyDE alone regressed 52.2 pp at Phase A (CIs do not overlap with the baseline) because hypothetical-document chunks displace the real bridge sessions below the top-K cutoff.
Recommended use: enable HyDE only on temporal-reasoning queries, or at ingest time for knowledge-base material where the answer phrasing differs systematically from question phrasing.
The Cognitive Memory Layer
The standalone Memory facade (over Brain) is sufficient for any TypeScript app that needs persistent retrieval. The cognitive layer, CognitiveMemoryManager, is a separate implementation over a vector-store-backed MemoryStore for agents that use personality-modulated encoding, working memory, the mechanisms below and consolidation; AgentMemory fronts either one.
Encoding (write time)
Every trace is created with a MemoryTrace shape that records:
- the content
- the embedding
- the source (which agent, which session, which message)
- the encoding timestamp
- an
encodingStrengthin [0, 1] modulated by:- the agent's HEXACO traits at encoding time, which weight content features: Openness novel content, Conscientiousness procedural content, Emotionality emotional content, Extraversion social content, Agreeableness cooperative content, Honesty-Humility ethical content
- the agent's current PAD mood (Pleasure/Arousal/Dominance from Mehrabian's Pleasure-Arousal-Dominance model): content whose valence matches the mood's encodes stronger
- the emotional intensity of the moment (Brown & Kulik's flashbulb-memory model: an event with intensity above 0.8 gets 2x strength and 5x stability multipliers)
- the Yerkes-Dodson arousal curve (encoding quality peaks at moderate arousal in an inverted U)
encodingStrength plus a per-trace stability parameter feed into the Ebbinghaus forgetting curve.
Decay (read time)
Strength decays exponentially with time on Hermann Ebbinghaus's 1885 forgetting curve:
S(t) = S₀ · e^(-Δt / stability)
stability is the curve's time constant: after one stability period a trace keeps about 37% of its strength. Successful retrieval grows stability (the desirable-difficulty effect: harder retrievals consolidate more). Co-retrieval of two traces tightens the edge between them via Hebbian weight updates ("neurons that fire together wire together"). The retrieval-feedback signal (used vs ignored) feeds the Strengthen step of the consolidation loop.
When decay drops a trace below the prune threshold (default 0.05), consolidation soft-deletes it. CognitiveMemoryManager's consolidation keeps traces with an emotional intensity of 0.3 or more whatever their strength, which matches the empirical finding that high-arousal memories persist longer than neutral ones (Cahill & McGaugh, 1998; LaBar & Cabeza, 2006); the Memory facade's loop prunes by strength alone.
Working memory (Baddeley slots)
CognitiveMemoryManager keeps a slot-based working memory following Baddeley's model (CognitiveWorkingMemory). The base capacity is 7 slots (workingMemoryCapacity); Openness above 0.6 adds a slot and Conscientiousness above 0.6 removes one, within 5 to 9. Each slot has its own activation level, which drops by 0.1 on each retrieval; the traces a retrieval returns are focused again, and a slot below 0.15 is evicted.
When the working memory is full, the lowest-activation slot is evicted. The trace stays in the long-term store; a slot only holds its id.
Spreading activation (ACT-R)
The memory graph stores edges between traces (same-session, same-entity, co-retrieved, derived-from). After scoring, CognitiveMemoryManager seeds a BFS with the five highest-scored traces, up to maxDepth (default 3) with activation halving per hop (decayPerHop 0.5). A retrieved trace the BFS reaches gets that activation as its graph signal and a new composite score, and the results are re-sorted; the five top traces then record a co-activation edge (Hebbian learning).
Spreading activation raises the rank of retrieved traces that are linked in the graph. It adds no trace that the search did not return.
Six-signal retrieval scoring
When the cognitive layer is active, the final retrieval score is a weighted composite:
score = 0.35 · similarity            (vector similarity)
      + 0.25 · current strength      (encoding strength after Ebbinghaus decay)
      + 0.10 · recency               (boost for a trace accessed within about a day)
      + 0.15 · emotional congruence  (current mood valence × trace valence, when positive)
      + 0.10 · graph activation      (spreading activation; 0 without a graph)
      + 0.05 · importance            (provenance confidence, scaled to 0.5–1)
The weights are DEFAULT_SCORING_WEIGHTS (RetrievalPriorityScorer.ts). A recall's scoringWeights replaces them for that call; the spreading-activation re-score uses the defaults. Personality does not change them.
The Eight Cognitive Mechanisms
On top of the encoding/decay/retrieval substrate, CognitiveMemoryManager runs eight neuroscience-grounded mechanisms when it is initialized with a cognitiveMechanisms config: {} turns all eight on with their defaults, and per-mechanism fields on CognitiveMemoryConfig override them (defaults.ts); without the config no mechanism runs. Six of them are scaled by a HEXACO trait: reconsolidation by Emotionality, RIF by Conscientiousness, involuntary recall by Openness, source confidence decay by Honesty-Humility, emotion regulation by Agreeableness and FOK by Extraversion.
Retrieval and prompt-assembly time
| Mechanism | Effect | Reference |
|---|---|---|
| Reconsolidation | Mutates trace.emotionalContext on access; the trace's emotional valence drifts toward the agent's current mood | Nader, Schafe & LeDoux 2000 |
| Retrieval-induced forgetting (RIF) | Suppresses the stability of competitor traces that were retrieved-but-not-cited | Anderson, Bjork & Bjork 1994 |
| Involuntary recall | When the memory context is assembled for a prompt, with probability 0.08 (scaled 0.5x to 1.5x by Openness), adds an unretrieved memory at least 14 days old with strength of at least 0.15 | Berntsen 2009 |
| Metacognitive feeling-of-knowing (FOK) | Detects when the retrieval cutoff is too tight (multiple candidates at similar scores near the boundary) and emits a signal the host can use to widen retrieval | Koriat 1993 |
Encoding time
| Mechanism | Effect | Reference |
|---|---|---|
| Schema encoding | Compares a new trace's embedding with cluster centroids: a novel trace's strength is multiplied by 1.3, a schema-congruent one's by 0.85. It runs only once the host passes centroids to the mechanisms engine's setClusterCentroids(); nothing in agentos sets them | Bartlett 1932; Anderson 1981 |
Consolidation time
| Mechanism | Effect | Reference |
|---|---|---|
| Temporal gist | Compresses verbatim content into a dense gist for traces older than 60 days with fewer than 2 retrievals | Reyna & Brainerd 1995 (fuzzy-trace theory) |
| Source confidence decay | Multiplies trace.stability per source type on each consolidation: user statements and tool results 1.0 (unchanged), observations 0.95, external sources 0.90, agent inferences 0.80, reflections 0.75 | Johnson, Hashtroudi & Lindsay 1993 source-monitoring framework |
| Emotion regulation | Reappraises high-arousal traces over time (suppression and reappraisal pathways from Gross's emotion-regulation model) | Gross 1998 |
The flashbulb guard skips RIF, temporal gist and emotion regulation on traces with encodingStrength >= 0.9, and the dead-trace guard skips RIF on traces with encodingStrength < 0.1. Reconsolidation has its own threshold, immuneAboveImportance, compared with encodingStrength; its default of 9 is above the 0–1 range of the strength, so no trace is immune unless the host sets it below 1. Disabled mechanisms return immediately.
Memory Consolidation (the background loop)
Consolidation is the analogue of slow-wave sleep. Each facade has its own implementation (Memory Consolidation).
ConsolidationLoop serves the Memory facade. A boolean flag makes a call that arrives while a run is in progress return at once with zero counts.
| Step | Action | LLM required |
|---|---|---|
| 1. Prune | Soft-delete traces whose decayed strength is below pruneThreshold (default 0.05). | No |
| 2. Merge | Deduplicate near-identical traces (cosine ≥ 0.95 with embedFn, or SHA-256 content match without). The trace with more retrievals survives with the tags of both; the other is soft-deleted. | No |
| 3. Strengthen | Read retrieval-feedback co-usage signals; record CO_ACTIVATED Hebbian edges in the memory graph (learning rate 0.1). | No |
| 4. Derive | Detect clusters of related memories (detectClusters, min size 5); LLM-synthesize a higher-level insight trace per cluster as type: 'semantic'. Bounded by maxDerivedPerCycle (default 5). Skipped entirely without an LLM invoker. | Yes |
| 5. Compact | Episodic-to-semantic migration: traces older than 7 days with retrieval count >= 3 change type to semantic. The content is unchanged. | No |
| 6. Re-index | Rebuild the FTS5 full-text index over memory_traces. Log the consolidation run. | No |
A personality-decay step runs between Compact and Re-index when a personality mutation store is configured. The Memory facade builds the loop with none of its options, so through the facade the merge step compares content hashes, the derive and personality-decay steps do not run, and a cycle runs only when consolidate() or the memory_reflect tool calls it.
ConsolidationPipeline serves CognitiveMemoryManager, hourly by default: a decay sweep (prunes below 0.05, keeps traces with emotional intensity of 0.3 or more), co-activation replay (shared-entity and temporal-sequence edges, with a graph), schema integration (LLM summaries of episodic clusters, with a graph and an LLM invoker), conflict resolution over CONTRADICTS edges, spaced-repetition reinforcement, the consolidation-time mechanisms above, and a retention sweep over an archive passed in its own config (365 days by default).
The verbatim archive is write-ahead where it is wired: the temporal-gist mechanism (when its resolved config carries an archive) and MemoryLifecycleManager call archive.store() and await success before changing the trace; if the archive write fails, the destructive operation aborts. CognitiveMemoryManager keeps its archive option for rehydrate() and passes it to neither the temporal-gist mechanism nor its consolidation pipeline. Rehydration (archive.rehydrate(traceId)) returns the original on demand without boosting encoding strength or incrementing retrieval count, and logs the access.
SqlStorageMemoryArchive wraps the same @framers/sql-storage-adapter interface as the brain, so archive tables (archived_traces, archive_access_log) live in the same database file by default. Postgres, IndexedDB, Capacitor SQLite, and sql.js are all supported through the shared adapter substrate (see The Storage Substrate above).
Multimodal RAG
AgentOS's core RAG APIs are text-first. Multimodal support is a composable pattern on top, built from MultimodalIndexer and its siblings; the asset table and the derivation steps belong to the host backend (Multimodal RAG):
- Store the binary asset (optional) plus metadata in the host's asset table (
media_assetsin the reference backend). - Derive a text representation: caption (image), transcript (audio), OCR (scanned doc), or extracted text (PDF, DOCX, HTML, Markdown, CSV).
- Index the derived text as a normal RAG document so the existing retrieval pipeline (vector, BM25, reranking, GraphRAG, HyDE) operates without any "special" multimodal database.
- Optionally add modality-specific embeddings (image-to-image, audio-to-audio) as an acceleration path.
The multimodal query routes take a retrievalMode of auto (text-first plus native modality when available), text (derived text only), native (modality embeddings only), or hybrid (fuse both). Query-by-image and query-by-audio go through the same flow: derive text from the query (caption/transcript/OCR), then route through the standard pipeline, with optional modality-native nearest-neighbor as a fast path.
Retrieval runs on derived text: AgentOS has no visual late-interaction retriever and no page-native document retrieval.
How the 85.6% Was Earned (Decomposition of the Lift)
Starting from the prior 76.6% headline (Tier 3 minimize-cost preset, CharHashEmbedder fallback, no reader router), the path to 85.6% decomposes into three independent contributions:
| Step | Lift | What changed |
|---|---|---|
1. Wire text-embedding-3-small instead of CharHashEmbedder | +6.6 pp | TR +14.5 pp, MS +14.5 pp; semantic embedding finds paraphrase-rich and multi-hop bridges that lexical hashing missed |
| 2. Drop OM-v11 routing, route everything through canonical-hybrid | +1.0 pp at gpt-4o reader | Avoids the SSP -13.4 pp loss from OM routing while accepting -4 pp on MS at gpt-4o (that gets recovered in step 3) |
| 3. Add ReaderRouter dispatch (gpt-5-mini for SSA/SSP/KU/MS, gpt-4o for TR/SSU) | +1.4 pp | SSP +10 pp dominates: 86.7% gpt-5-mini vs 76.7% gpt-4o on canonical |
| Total | +9.0 pp (76.6 → 85.6) |
Cost-Pareto improvements at the same accuracy delta:
- 4.6x cheaper per correct ($0.0410 → $0.0090) by dropping OM-v11's per-session observer pipeline and routing to gpt-5-mini for 53% of queries.
- 5.3x faster average latency (21,042 ms → 4,001 ms) for the same reason.
- 15.4x faster p95 latency (111,535 ms → 7,264 ms): OM-v11 routing imposed 60-120 seconds per OM-routed case as the per-session observer pipeline ran; canonical-only avoids that tail entirely.
The configuration was stress-tested with 7 adjacent knobs at full Phase B: every adjacent setting (--reader-top-k 30, --hyde, --rerank-candidate-multiplier 5, --retrieval-config-router minimize-cost-augmented, --policy-router-preset balanced, --policy-router-preset maximize-accuracy, text-embedding-3-large) regresses. The 85.6% configuration is empirically Pareto-optimal in the tested parameter space.
How the 70.2% on M Was Earned
LongMemEval-M's haystacks exceed every production LLM context window (1.5M tokens > GPT-4o's 128K). Retrieval saturates differently than at S scale: smaller chunk pools per session, more sessions per haystack, and a much harder multi-session bridge problem.
The M-tuned headline configuration:
NODE_OPTIONS="--max-old-space-size=8192" pnpm exec tsx src/cli.ts run longmemeval-m \
  --reader gpt-4o \
  --memory full-cognitive --replay ingest \
  --hybrid-retrieval --rerank cohere \
  --embedder-model text-embedding-3-small \
  --reader-router min-cost-best-cat-2026-04-28 \
  --reader-top-k 5 \
  --concurrency 5 \
  --bootstrap-resamples 10000
Key M-specific knobs:
--reader-top-k 5(was 50 in the prior 57.6% headline). The single biggest M-specific lift: +12.6 pp from 57.6% to 70.2%. Wider top-K dilutes the reader prompt with topically adjacent but irrelevant sessions; M's session count (500 per haystack) means the rerank pool already over-prunes, and feeding 50 chunks to the reader introduces more noise than signal.- HyDE enabled for multi-session bridge queries. Cost-Pareto win on TR; on M, ablation showed HyDE-off is within statistical noise of the headline (69.2% vs 70.2%), so HyDE is cost-neutral on M, not a clear win.
- Cohere rerank-v3.5 candidate multiplier x5. Wider candidate pool gives the cross-encoder more sessions to disambiguate among. At multiplier x10 (Phase B ablation), accuracy drops to 60.0% at higher cost.
- Reader Router picking gpt-5-mini for SSA/SSP/KU/MS, gpt-4o for TR/SSU. Same calibration as S.
Compared with the LongMemEval paper's GPT-4o configurations from Wu et al., ICLR 2025, Table 3:
| Configuration | Accuracy |
|---|---|
| Round-level Top-5 K=V+fact | 65.7% |
| Session-level Top-5 K=V+fact | 71.4% |
| Round-level Top-10 K=V+fact (paper's strongest) | 72.0% |
| AgentOS at Top-5 reader budget | 70.2% |
AgentOS at Top-5 sits 4.5 above the round-level baseline (65.7%) and 1.2 below the session-level (71.4%). At the harder Top-5 reader budget, AgentOS is 1.8 below the paper's strongest GPT-4o result (72.0%, Top-10).
Among open-source memory libraries with publicly reproducible runs (per-case run JSONs at fixed seed, single-CLI reproduction), AgentOS is the only one on the public record above 65% on M. Every other vendor (Mem0 v3 93.4%, Mastra OM 84.2-94.9%, Hindsight 91.4%, Zep 71.2%, EmergenceMem 86%, Supermemory 81.6-85.2%, MemMachine 93%, Memoria 88.78%, agentmemory 96.2%, Backboard 93.4%, ByteRover 92.8%) publishes only the easier S variant. M's 1.5M-token haystacks exceed every production LLM context window, so vendors with prompt-stuffing or compression-based architectures avoid the variant.
Negative Findings (What Was Tried and Dropped)
Every sentence above is paired with at least one Phase B negative finding that disqualifies the alternative. The 8 documented architecture-level negative findings:
| Probe | Outcome | Why dropped |
|---|---|---|
| Stage L Anthropic Contextual Retrieval at S | Within CI of canonical-hybrid baseline; no measurable lift | Pre-pending session summaries to every chunk did not extract retrieval signal not already captured by Cohere rerank |
| Stage I Mem0-v3-style entity-linking re-rank | Regressed 1-2 pp at Phase B | Entity-link extraction at re-rank time added latency without recall improvement on this category mix |
| Stage H hierarchical retrieval | Within CI; cost premium | Two-stage retrieval (session-level then chunk-level) didn't beat single-stage canonical |
| Two-call reader compounded with M-tuned | Regressed 11.6 pp on M (58.6% vs 70.2%) | Extract-then-answer adds reader cost without lifting M accuracy past Top-5 baseline |
| M-tuned flags compounded on S | Regressed | M-specific tuning (top-K=50, candidate x5, HyDE) over-prunes S's smaller chunk pool |
| All-OM Mastra-architecture clone on S | Regressed on SSP -13.4 pp | OM observer pipeline costs SSP accuracy at gpt-4o reader |
| gpt-4o classifier upgrade (vs gpt-5-mini) | Regressed 0.4-1.6 pp aggregate; +44% cost | More aggressive category re-categorization didn't help on this category mix |
text-embedding-3-large (3072-dim) | -2.2 pp accuracy + 20x latency | Larger embedding does not lift recall at this stack |
Other Phase B negatives:
- Cohere rerank-v4.0-pro vs rerank-v3.5: -1.0 pp at point estimate, more expensive per call. Definitively dropped.
- HyDE-on-MS-only S-tuned router (pre-validation hypothesis): -52.2 pp on multi-session at S. HyDE alone hurts MS at every haystack scale; the dispatch primitive ships in source for future calibration but the HyDE-on-MS preset is refuted.
- Wider rerank pool on MS-only at S (
topk50-mult5-on-MS): -41.1 pp on MS. At S scale the canonical pipeline is at the empirical accuracy ceiling for MS; broadening the candidate pool dilutes more than it helps. To push MS at S scale, the next architectural lever needs to be a different signal (typed graph traversal) or a model-tier swap (gpt-5 reader). - gpt-5 reader on TR/SSU: Phase A small-sample lift (87.0% at N=54) compressed to -2.4 pp at full N=500. Definitively dropped.
top-K 3on M: -5.0 pp vs Top-K=5. Floor on M reader-top-K is 5.rerank-candidate-multiplier 10on M: -10.2 pp vs multiplier x5. Wider candidate pool over-prunes M's session count.
Every dropped probe ships its run JSON under agentos-bench/results/runs/ for independent inspection.
Vendor Comparison and Caveats
Direct accuracy comparison (LongMemEval-S, full N=500 except where noted; every row uses a gpt-4o reader except the AgentOS ReaderRouter row, which routes gpt-5-mini on four of the six question types):
| System | Accuracy | $/correct | p50 latency | License | Notes |
|---|---|---|---|---|---|
| AgentOS canonical-hybrid + ReaderRouter | 85.6% | $0.0090 | 3,558 ms | Apache-2.0 | This stack |
| EmergenceMem Internal | 86.0% | not published | 5,650 ms | closed-source SaaS | Hosted at emergence.ai; cannot install, fork, or self-host |
| Mastra OM gpt-4o (gemini-flash observer) | 84.23% | not published | not published | Apache-2.0 | Level with AgentOS at a matched gpt-4o reader; cross-provider observer pipeline |
| AgentOS canonical-hybrid, gpt-4o on every question | 84.2% | not published | not published | Apache-2.0 | The matched-reader comparison point: run 18-41, footnote canonical-reader-router-pb in LEADERBOARD.md |
| EmergenceMem Simple Fast (rerun in agentos-bench) | 80.6% | $0.0581 | 3,703 ms | no LICENSE file | Apache-2.0 grants no license to redistribute the upstream main.py; we measured it for accuracy comparison only |
| Supermemory gpt-4o | 81.6% | not published | not published | proprietary | -4.0 pp |
| Zep (self / independent reproduction) | 71.2% / 63.8% | not published | not published | varied | Self-reported number gamed; independent reproduction far below |
Cross-provider numbers are excluded from the headline cell because their methodology disclosures don't admit reproduction:
- Mastra OM 94.87% with gpt-5-mini reader + gemini-2.5-flash observer (different reader and observer)
- agentmemory 96.2% with Claude Opus 4.6 (different reader)
- MemMachine 93.0% with GPT-5-mini (different reader)
- Hindsight 91.4% (unspecified backbone)
The cross-reader frontier across all reader tiers and judge configurations spans 89-96%. The 85.6% AgentOS headline routes gpt-5-mini on four of the six question types; pinning the reader to gpt-4o (84.2%) keeps the comparison apples-to-apples.
Methodology hygiene we ship
- Bootstrap 95% confidence intervals at 10,000 Mulberry32 resamples (seed 42) for every reported aggregate
- Judge false-positive-rate probes per benchmark: LongMemEval-S 1% [0%, 3%], LongMemEval-M 2% [0%, 5%], LOCOMO 0% [0%, 0%]
- Per-cell run JSON at seed 42 under
results/runs/(LongMemEval-M run JSONs exceed GitHub's 100 MB recommendation and are gitignored; their--summary.jsonsiblings are committed) - Per-vendor caveats on every cross-vendor row (which dimensions are apples-to-apples, which are not)
- No claims without complete standalone runnables in the headline table. Vendors that publish only blog-post numbers without a single-CLI reproduction appear in narrative paragraphs as published numbers with explicit provenance, not in measured cells.
LOCOMO caveat
LOCOMO's answer key has 6.4% ground-truth errors per Penfield Labs and the default judge accepts 62.81% of intentionally wrong answers. Any LOCOMO score gap below ~6 pp is inside judge noise. AgentOS reports LOCOMO with that caveat or not at all.
Feature comparison vs. other memory libraries
The vendor table above measures accuracy at a matched reader. The table below measures feature coverage: which cognitive and operational concerns each library handles at all.
| Feature | AgentOS Memory | mem0 | Cognee | Letta (MemGPT) | Mastra |
|---|---|---|---|---|---|
| Storage | SQLite/Postgres/IndexedDB/Capacitor via one adapter | Qdrant/Chroma/Postgres | Neo4j + vector | Postgres + Chroma | Postgres + Pinecone |
| Personality modulation | HEXACO 6-trait encoding bias | — | — | — | — |
| Forgetting curve | Ebbinghaus exponential | — | — | — | — |
| Spaced repetition | Interval doubling, desirable difficulty | — | — | — | — |
| Working memory | Baddeley slots (5-9, trait-modulated) | — | — | FIFO context window | Fixed sliding window |
| Mood-aware retrieval | PAD mood congruence (0.15 weight) | — | — | — | — |
| Memory graph | SQLite-backed with spreading activation | Simple key-value | Neo4j graph | — | — |
| Self-improvement | 6-step consolidation (prune/merge/strengthen/derive/compact/reindex) | Manual CRUD | Batch re-processing | Edit-based | — |
| Retrieval signals | 6-signal composite | Cosine similarity | Cosine + graph | Cosine similarity | Cosine similarity |
| Document ingestion | 3-tier (PDF, DOCX, HTML, Markdown, CSV, JSON, URLs) | Text only | PDF, text | Text only | Text only |
| Import/Export | SQLite, JSON, Markdown, Obsidian, ChatGPT, CSV | JSON | — | JSON | — |
| Offline-first | Zero network required | Requires vector DB | Requires Neo4j | Requires server | Requires cloud |
| Provenance tracking | Full source type, confidence, verification count | — | Basic | — | — |
Reproducing the Numbers
Single-CLI reproduction. The bench is source-only (clone and run via local CLI; not published to npm).
git clone https://github.com/framerslab/agentos-bench
cd agentos-bench
pnpm install
pnpm build

# Set OPENAI_API_KEY and COHERE_API_KEY in your environment
# Download LongMemEval-S dataset per upstream instructions at
# https://github.com/xiaowu0162/LongMemEval into data/longmemeval/longmemeval_s.json

# Reproduce the LongMemEval-S 85.6% headline:
NODE_OPTIONS="--max-old-space-size=8192" pnpm exec tsx src/cli.ts run longmemeval-s \
  --reader gpt-4o \
  --memory full-cognitive --replay ingest \
  --hybrid-retrieval --rerank cohere \
  --embedder-model text-embedding-3-small \
  --reader-router min-cost-best-cat-2026-04-28 \
  --concurrency 5 \
  --bootstrap-resamples 10000

# Reproduce the LongMemEval-M 70.2% headline:
NODE_OPTIONS="--max-old-space-size=8192" pnpm exec tsx src/cli.ts run longmemeval-m \
  --reader gpt-4o \
  --memory full-cognitive --replay ingest \
  --hybrid-retrieval --rerank cohere \
  --embedder-model text-embedding-3-small \
  --reader-router min-cost-best-cat-2026-04-28 \
  --reader-top-k 5 \
  --concurrency 5 \
  --bootstrap-resamples 10000
Expected wall-clock (S): ~10-15 min at concurrency 5. Expected cost: ~$3.84 in OpenAI/Cohere fees.
The routing primitives the bench uses ship in @framers/agentos/memory-router (MemoryRouter, selectReader()), so a consuming app gets the same routing decisions:
import OpenAI from 'openai';
import { Memory } from '@framers/agentos';
import { selectReader } from '@framers/agentos/memory-router';

const openai = new OpenAI();
const mem = await Memory.createSqlite('./memory.sqlite', {
  embed: async (text) =>
    (await openai.embeddings.create({ model: 'text-embedding-3-small', input: text })).data[0].embedding,
});

await mem.remember('The user moved to Lisbon in March.');
const hits = await mem.recall('Where does the user live?');

// The reader model for the category a MemoryRouter classifier returned:
const readerModel = selectReader('single-session-user', 'min-cost-best-cat-2026-04-28'); // 'gpt-4o'
Source File Map
For readers who want to trace the architecture into code:
| Subsystem | Path |
|---|---|
| Memory facade | src/cognition/memory/io/facade/Memory.ts |
| Brain (SQLite + Postgres + adapter entry points) | src/cognition/memory/retrieval/store/Brain.ts |
| Storage adapter (cross-platform substrate) | src/ in framerslab/sql-storage-adapter |
| SQL Dialect / FTS abstraction / BLOB codec | src/dialects/, src/fts/, src/codecs/ in framerslab/sql-storage-adapter |
| Cognitive memory orchestrator | src/cognition/memory/CognitiveMemoryManager.ts |
| Encoding model | src/cognition/memory/core/encoding/EncodingModel.ts |
| Decay model (Ebbinghaus) | src/cognition/memory/core/decay/DecayModel.ts |
| Working memory (Baddeley) | src/cognition/memory/core/working/CognitiveWorkingMemory.ts |
| Memory graph + spreading activation | src/cognition/memory/retrieval/store/SqlMemoryGraph.ts, src/cognition/memory/retrieval/graph/SpreadingActivation.ts |
| Eight cognitive mechanisms | src/cognition/memory/mechanisms/ |
Consolidation (Memory facade, CognitiveMemoryManager) | src/cognition/memory/pipeline/consolidation/ConsolidationLoop.ts, src/cognition/memory/pipeline/consolidation/ConsolidationPipeline.ts |
| Verbatim archive | src/cognition/memory/archive/SqlStorageMemoryArchive.ts |
| Hybrid retriever (BM25 + dense + Cohere) | src/cognition/memory/retrieval/hybrid/HybridRetriever.ts |
| HyDE retriever | src/cognition/rag/HydeRetriever.ts |
| Multimodal indexer | src/cognition/rag/multimodal/MultimodalIndexer.ts |
Ingest router (IngestRouter.ts) | src/orchestration/pipeline/ingest/ |
Memory router + adaptive variant (MemoryRouter.ts, adaptive.ts) | src/orchestration/pipeline/memory/ |
Reader-model lookup (selectReader()) | src/orchestration/pipeline/memory/reader-router.ts |
Read router strategy dispatch (ReadRouter.ts) | src/orchestration/pipeline/read/ |
| Cognitive pipeline (composition) | src/orchestration/pipeline/ |
| Bench harness | src/ in framerslab/agentos-bench |
| Run JSONs | results/runs/ in framerslab/agentos-bench |
| Leaderboard | results/LEADERBOARD.md in framerslab/agentos-bench |
Further Reading
- Cognitive Memory — full primary-source citations for every cognitive-science model used, plus the 8-mechanism implementation reference
- Memory Operations — auto-ingest pipeline, agent-facing memory tools, import/export across 6 formats
- Cognitive Pipeline — the classifier-driven dispatch composition
- Ingest Router, Memory Router, Read Router — per-stage primitives
- Adaptive Memory Router — self-calibration for non-LongMemEval workloads
- HyDE Retrieval, Multimodal RAG, Memory Consolidation — specialty topics
- SQLite Brain Storage, Postgres + pgvector Backend — backend-specific schema, WAL/MVCC tradeoffs, multi-tenant patterns
@framers/sql-storage-adapter— full storage substrate: adapter matrix, SQL dialect translation, FTS abstraction, BLOB codec, cross-platform sync- Bench Leaderboard — full benchmark tables with confidence intervals and per-category breakdowns
- Transparency Audit — what the headline numbers don't say (LOCOMO answer-key error, judge bias, vendor comparison gaming)